02 - Feed-forward Neural Network
2026-01-31
Neural networks are now ubiquitous and are the foundation for Large Language Models (LLMs).
This article will explain the architecture of a simple Feed-forward Neural Network (FFNN), starting from first principles.
A simple perceptron
Neural networks are not new. Back in the 1950s, scientists were already researching perceptrons. A perceptron is a function that takes in an input vector, applies a higher order linear transformation to explore hidden dimensions, an activation function to fit complex relationship in the higher order space.
Like other optimization problems, we can then use a loss function to compare the result of the perceptron with the expected value.
To illustrate this, lets look at
A brief description of Neural Networks
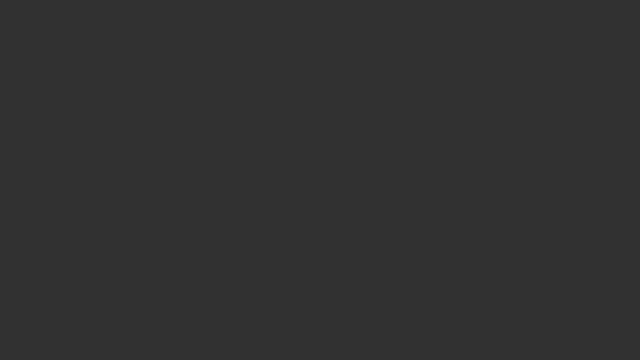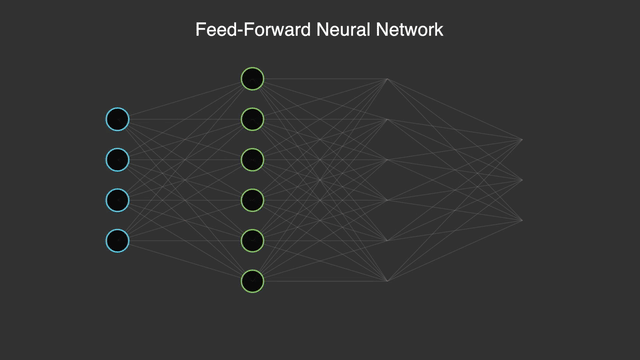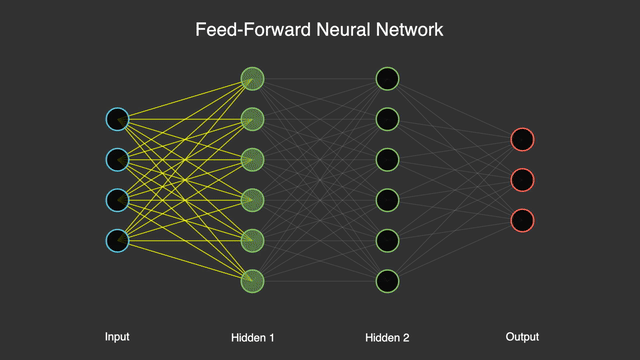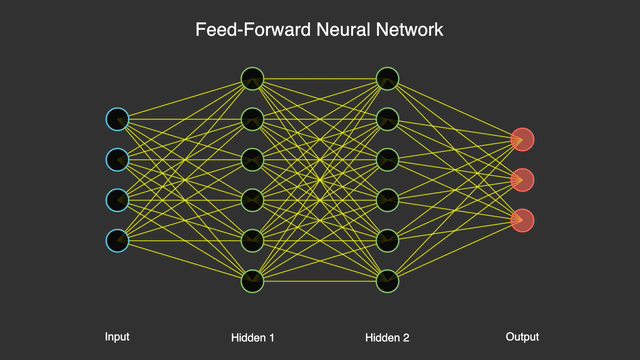
A feed-forward neural network (FFNN) is the simplest artificial neural network. It is composed of nodes that are organised in layers. Each layer is made up of a linear transformation of its input vector with a weights matrix and a bias sum. An activation function which centers the output of the node to be read by the next layer is used to ensure the input values of the next layer fall in a reasonable range.
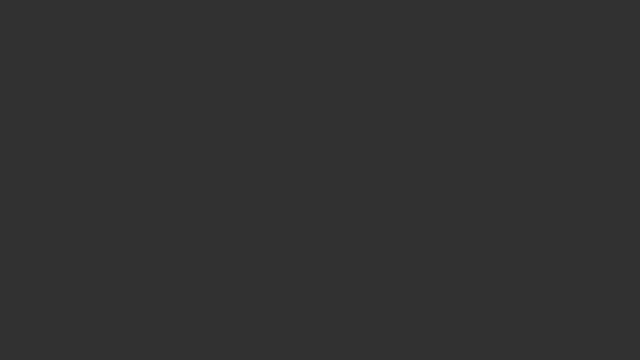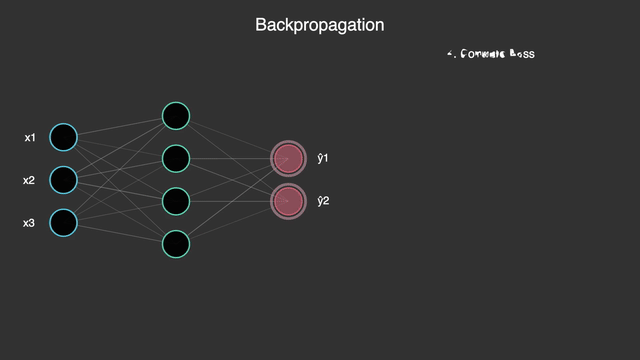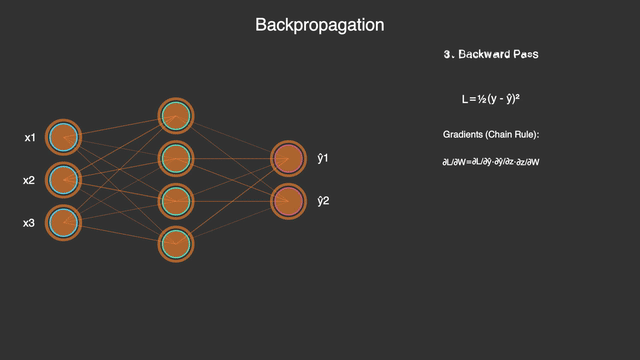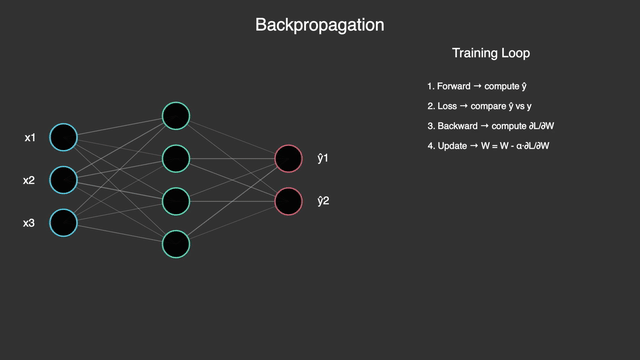
The process of training a neural network is as follows:
- Featurise your dataset into a set of vectors.
- Feed the input vectors through the neural network.
- A cost function associated with the output of the last layer is used to calculate how far off the overall output is from the intended value.
- Apply back propagation through the network updating the values of the weights and bias parameters using a learning rate
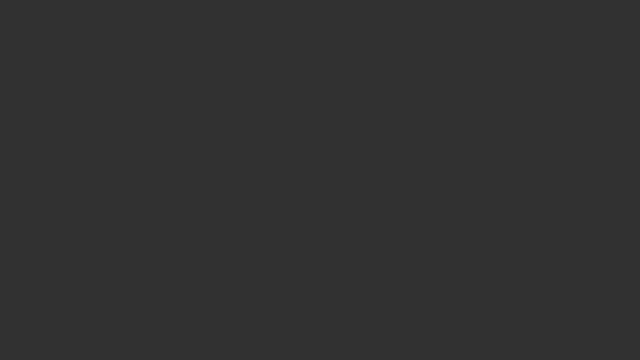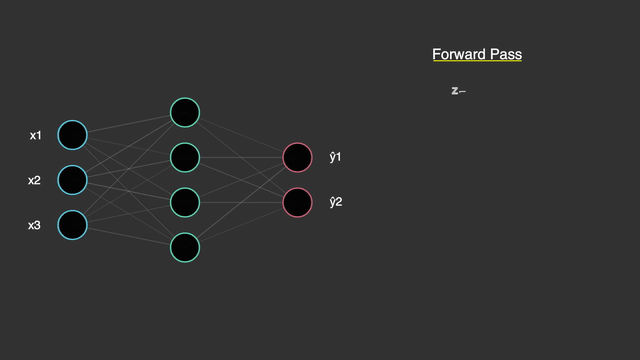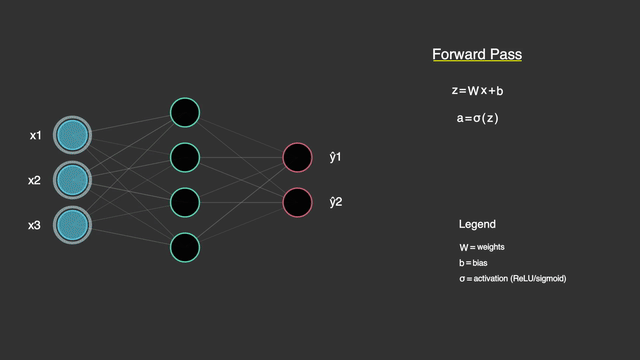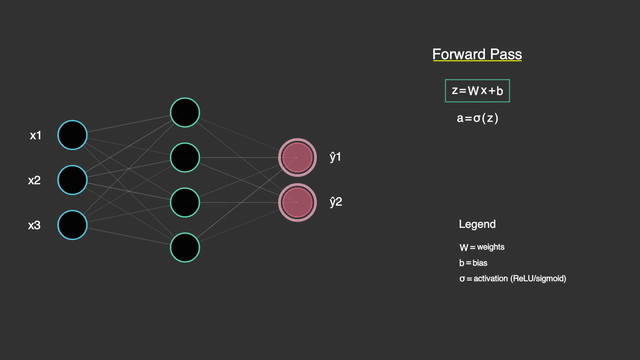
The following illustrates the above process:
The following hyper-parameters are required for building a FFNN:
- activation function to be used at a given layer.
- number of layers.
- learning rate.
Derivations
There are two equation to remember when dealing with neural networks is
Linear transformation:
where \(W\) represents a matrix of weights, \(X\) is our input and \(b\) is a bias.
What this does is project the points in the input vector space into a new space. We update the values of \(W\) (the linear transformation) in a way to minimise the loss function (a.k.a. how far we are from predicting the right output).
Activation
This is used to add non-linear (a.k.a. complex patterns) to the learning between the layers.
FFNN have a lot of parameters. To simplify, let's consider a small FFNN with 3 layers:
- Input layer: vectors of dimension 3
- Hidden layer: vector of dimension 2
- Output layer: vector of dimension 1
So a feed forward would look like this
input layer -> hidden layer:
hidden layer -> output layer
We then apply some cost function (e.g. MSE or Cross Entropy).
Geometric intuition behind neural networks
Backprogagation
The Loss function (here we are using MSE) but there are other loss functions is a function of the following form
Given that our resultant estimation is defined in terms of \(W^n\) weights and \(b^n\) biases, we can write \(\hat{y}\) as follows:
where \(F\) represent the forward propagation with linear transformation and activation function explained above.
We can now use a loss function (here MSE) for instance:
where the last equality holds from above.
Similar to 01: Linear Regression, we apply gradient descent to reduce the error between the measured and actual:
We apply this gradient descent for each layer in the neural network.
Let's look at the last layer in the neural network \(n\)
Setting \(u = Y - F(W^n, b^n)\), we get
Let's compute \(\frac{\partial{u}}{\partial{W^{n}}}\) Recall that only \(-F(W^n, b^n)\) actually is impacted by \(W^n\).
Recall that \(F(W^{n}, b^{n}) = \sigma(W^{n}Z^{n-1} + b^{n})\) where \(Z^{n-1}\) is the result of the previous layer.
This means
Applying chain rule again, setting \(v = W^{n}Z^{n-1} + b^{n}\), this gives
Recalling that \(\frac{\partial{v}}{\partial{W^{v}}} = Z^{n-1}\), we get
Similar for \(b^n\), we get $$ \frac{\partial{J(W^{n},b^{n} )}}{\partial{b^{n}}} = -\frac{\partial{\sigma(v)}}{\partial{v}} $$
Looking at the \(ith\) layer now:
← 01 - Linear regression | Claude Code: Lessons from the Trenches →